Why the agent bill grows
This block works out why the input bill of an agent run grows faster than its number of steps, what prompt caching changes, and what quietly switches caching off. Prices were read from the vendors' pages on 2026-11-10. They change often, so treat them as worked examples.
A disputed refund at Northwind Goods takes the support agent 20 model calls. An ordinary case takes 10. Finance expected the disputed case to cost twice as much. It costs more than three times as much.
Reading the notes out again
Back to the colleague on the phone, who forgets everything when you hang up. Every time you ring back, you read out the whole call so far, and you pay per word read. The first reading is short. The twentieth is long, and most of it is words you have already paid for.
Take three numbers from this run:
- Every call starts with 6,000 tokens: system prompt, tool schemas, the customer's message.
- Each step adds 1,500 tokens: 300 the model wrote and 1,200 from the tool result.
- Your code resends all of it on each call.
So call 1 sends 6,000, call 2 sends 7,500, and call 20 sends 34,500.
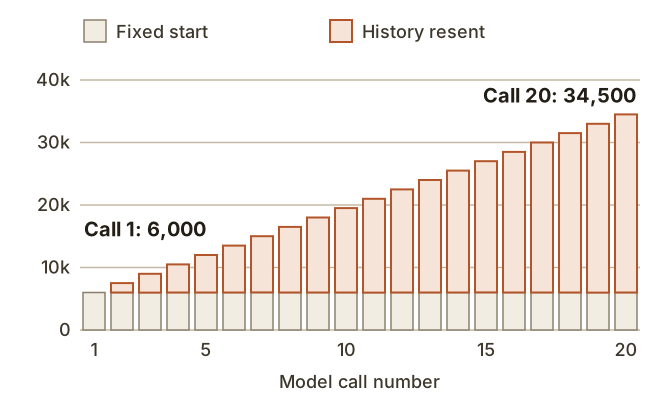
Add up the bars and you get a formula, with n calls, a start of P tokens and d tokens added per step:
total input = n * P + d * n * (n - 1) / 2Calls | Total input tokens |
|---|---|
10 | 127,500 |
20 | 405,000 |
40 | 1,410,000 |
Going from 20 calls to 40 multiplies input by 3.5. The first term grows with n, the second with n squared. In short runs the first term hides the second, so a quick test looks harmless.
On Claude Sonnet 5.5, input is $2 per million tokens and output $10. The 20-call run costs $0.81 of input and $0.06 of output, so input is 93% of the bill.
The copy on the desk
Suppose your colleague keeps a copy of what you read and leaves it on the desk for five minutes. You still read from the top. While your words match the copy, they only follow along with a finger, which is quick and cheap. At the first word that differs, the copy stops being useful and they listen properly from there on.
That is prompt caching. The provider stores its processed state for the start of a prompt, the prefix. On an API like Anthropic's you still send the whole history on every call, and all of it is still context for the model. You pay less for the part that matches.
On Anthropic's Messages API you opt in. Your code adds one field:
{
  "model": "claude-sonnet-5-5",
  "max_tokens": 1024,
  "cache_control": {
    "type": "ephemeral"
  },
  "system": "You are the Northwind support agent...",
  "messages": []
}
Call by call, on this setup:
Call 1. The API finds nothing stored, processes the prompt and stores it. This is a write, at 1.25 times the input price for the default 5-minute lifetime.
Call 2. The API finds the same prefix and reads it. On Sonnet 5.5 a read costs 0.05 times the input price. The block added since call 1 is written.
Each read refreshes the 5 minutes at no extra cost. The clock starts when a request starts, so a slow response uses it up too. If the run stops longer than that, the next call writes everything again.
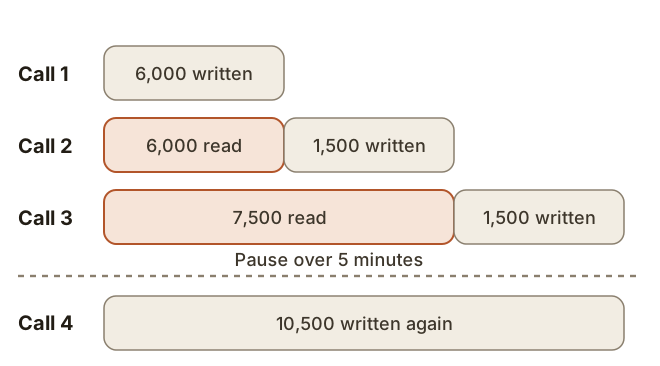
Call 20 reports this in its usage:
{
  "usage": {
    "input_tokens": 0,
    "cache_read_input_tokens": 33000,
    "cache_creation_input_tokens": 1500,
    "output_tokens": 300
  }
}
The total input is the sum of the first three fields. On Anthropic's API, input_tokens counts only what comes after the last cache breakpoint, so a dashboard that reads that field alone shows almost nothing.
Calls | Written | Read | Output | Total | Without cache |
|---|---|---|---|---|---|
20 | $0.09 | $0.04 | $0.06 | $0.18 | $0.87 |
50 | $0.20 | $0.21 | $0.15 | $0.55 | $4.43 |
100 | $0.39 | $0.79 | $0.30 | $1.47 | $16.35 |
Each cell is rounded to the cent, so a row can differ from its sum by a cent.
Look at the Read column. Caching cuts the price per token and leaves the shape alone: reads still grow with n squared. By 100 calls they are more than half of the bill. Output gets no discount at all.
What breaks the match
The match runs from the start of the prompt and cannot go past the first difference. On Anthropic's API a read also needs an entry that an earlier request wrote at a cache breakpoint. The order is tools, then system, then messages, and a change at one level invalidates that level and the ones after it.
 system:
-  Current time: 2026-11-10T14:03:22Z. You are the Northwind support agent...
+  You are the Northwind support agent...
 messages:
   ...earlier steps...
+  Current time: 2026-11-10T14:03:22Z
So stable content goes first, and whatever changes goes last.
On Anthropic's API that takes one more step here. Top-level cache_control puts the breakpoint on the last block, and in this layout the last block changes on every call, so nothing would be read. Put cache_control on the last block that stays the same, as the docs advise. The time then counts as input_tokens.
What happened | What you lose on Anthropic's API |
|---|---|
A timestamp or request id early in the prompt | With one breakpoint at the end, every read on every call |
A tool added, removed or reworded | The whole cache |
A sentence of the system prompt edited | System and messages |
| Messages |
A pause over 5 minutes, say for a human approval | Everything. A 1-hour lifetime exists, with writes at 2 times the input price |
A prompt under the model's minimum, 512 tokens on Sonnet 5.5 | No error. Both cache fields in |
OpenAI's guide gives the same advice for tools: keep definitions, ordering and schemas consistent.
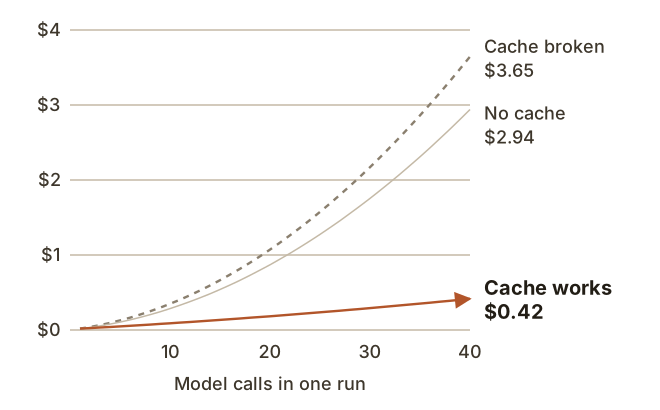
A broken cache is worse than no cache. With a new timestamp on each call, nothing is ever read, and every token is billed at the write price.
Vendors differ
Checked on 2026-11-10:
| Switched on | Write | Read |
|---|---|---|---|
Anthropic Messages API | You add | 1.25x for 5 minutes, 2x for 1 hour | 0.1x; 0.05x on Opus 5.5 and Sonnet 5.5; 0.025x on Fable 5.1 and 5.2 |
OpenAI, GPT-5.6 and later | By default | 1.25x for 30 minutes, 2.5x for 12 hours in the Responses API | 0.1x; 0.05x on GPT-6.1 Sol and Terra |
Older OpenAI models follow different rules, and Gemini 2.5 and newer cache implicitly by default. Read the price page for your exact model before you build an estimate on it.
Conclusion
- Each call resends the history, so total input grows roughly with the square of the calls.
- Caching makes the matching prefix much cheaper. Reads still grow with the square, and output is not discounted.
- Keep stable content first and changing content last, and check the cache fields in
usage.