One agent or a swarm
This block explains when several agents beat one, what they cost, and how far the published numbers can be trusted.
Northwind's team wants to split the support agent into a refund agent, a replacement agent and a shipping agent, all working on each ticket at once. Operations asks for something else: compare late-delivery penalties across 14 carrier contracts. Both get called multi-agent. They are very different jobs.
Three archives and one customer
Your colleague on the phone gets helpers. Send three helpers to three archives and each comes back with one page. What one finds does not change what another should look for, so they never need to talk.
Now put two helpers on two phones with the same customer. One promises a refund, the other promises a replacement, and neither heard the other.
In Anthropic's definition, a multi-agent system is several model instances with separate conversations, coordinated by code. People use "swarm" loosely for this, though Anthropic lists agent swarms as one pattern among several. A straightforward form, and the one used here, is a lead agent, or orchestrator, that hands work to subagents.
The fan-out, step by step
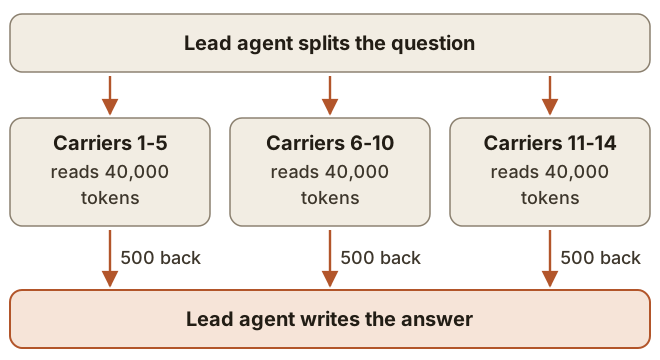
- The lead agent reads the request and writes a brief for each subagent. In Anthropic's research system, short briefs led to duplicated searches and misread tasks.
- Your code starts the subagents in parallel, each with its own context.
- Each subagent runs its own loop and condenses what it found.
- The lead agent reads the short reports and writes the answer.
A brief for the contract job:
{
  "objective": "Find late-delivery penalty terms for carriers 1 to 5",
  "output": {
    "carrier": "string",
    "penalty_cents_per_day": "number or null",
    "clause": "string"
  },
  "tools": [
    "read_contract",
    "search_tickets"
  ],
  "out_of_scope": "Carriers 6 to 14. Do not contact any carrier."
}
Both tools only read, so the subagents cannot change anything another one depends on. They can still repeat work or disagree, so the lead agent checks what comes back.
When the work writes
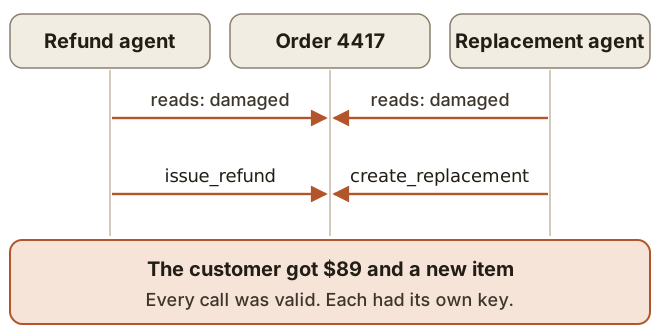
Cognition described this failure in June 2025 with two principles: agents need each other's full context, and actions carry implicit decisions that can conflict. Idempotency keys do not help here, because a refund and a replacement are two different operations.
An order is state, and each step depends on the last, so one agent should own it. In January 2026 Anthropic gave the same advice: work that needs shared state stays together, and split by context, not by role. In one of its experiments, agents split into planner, implementer, tester and reviewer spent more tokens coordinating than working.
In April 2026 Cognition reported multi-agent setups that do work for its coding agents, with a narrower rule: "writes stay single-threaded". The extra agents advise or review.
Two numbers, two baselines
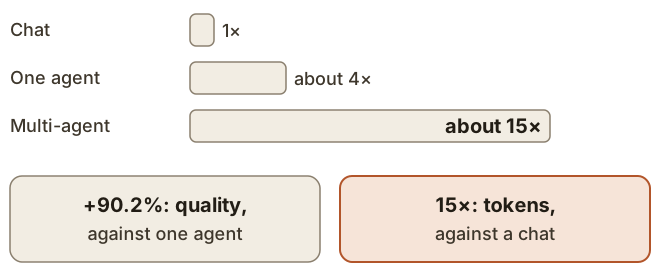
Anthropic's Research system, with an Opus 4 lead and Sonnet 4 subagents, beat a single Opus 4 agent by 90.2% on an internal research eval. Separately, its agents typically used about 4× the tokens of a chat, and multi-agent systems about 15×.
So "15 times more expensive than one agent" is wrong. Dividing the two ratios gives about 3.75× over one agent, which is our arithmetic on rounded figures. Anthropic's 2026 article says 3 to 10× for equivalent tasks in its testing.
The 90.2% comes from a vendor's internal eval, Anthropic says these systems excel especially at breadth-first queries, and the post does not say the single agent got the same budget. Anthropic writes that these systems "work mainly because they help spend enough tokens". On BrowseComp, a test of finding hard-to-locate information on the web, token use alone explained 80% of the variance in performance. The gain may be the architecture, the spending or both.
Do not count on speed either. Parallel subagents finish sooner than sequential ones, but Anthropic says multi-agent systems often take longer overall than a single agent.
With budgets controlled
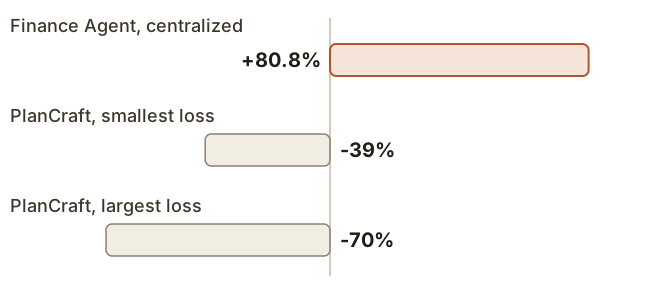
A controlled study of 260 configurations on six benchmarks found the sign depends on the task. On PlanCraft, a planning benchmark, traces showed short sequential work being delegated for no benefit. Its authors also fitted a selection rule: above about 45% single-agent success, it predicts zero or negative gains from adding agents.
Source | Setting | Result | Limits |
|---|---|---|---|
Anthropic, 2025 | Internal research eval | +90.2% against one agent | Unpublished eval, budgets not stated as matched |
Scaling study, 2025-26 | Six benchmarks, no user, matched compute | From +80.8% to -70% | Its 45% single-agent threshold is a selection rule, not a universal cutoff |
Dual-control study, October 2026 | About 7,950 simulated support chats under a written policy | Weighted mean -28 points over 12 cells (95% CI -44 to -12) | Preprint, simulated users, one design whose planner never saw the tool schemas |
MAST, 2025 | 7 open-source frameworks | 41% to 86.7% of runs failed | That figure has no single-agent comparison |
The third row is closest to Northwind. A simulated customer gives information turn by turn, and in one of the three domains the customer can act too, which is what dual-control means. A cell is one model on one domain. A centralized multi-agent system was worse in 12 of the 13 cells that passed the validity checks and tied in the other, and it did not measurably reduce wrongful database writes. It also lost on the two cells clearly below 45%, where the rule predicts a gain. The tied cell gained 10 points only under a different simulated customer.
The budgets there were not equal: the multi-agent system could spend up to 4 times the single agent's 75th-percentile completion tokens. With no ceiling, on the three cells tried, it at best drew level, at 5.5 times the single agent's median tokens.
A vendor's gain and a benchmark's loss each describe particular designs on particular tasks. Neither tells you what will happen on your tickets.
How to decide
Anthropic reports teams spending months on multi-agent architectures, then matching them by improving the prompt of a single agent. So start with one.
Add subagents for independent reads, for work too large for one context, or for a narrow reading job that would fill the main context. Keep writes to shared state, like an order, on one thread. Then test both designs on your own tasks at the same token budget, and compare the price per resolved ticket.
For Northwind, the contract comparison can fan out. The ticket stays with one agent.
Conclusion
- Fan out independent reads. Keep stateful work like an order with one writer.
- +90.2% is against one agent and 15× is against a chat, so do not combine them into one claim.
- With budgets controlled, results run from large gains to large losses depending on the task.
- Compare both designs on your own tasks at the same budget.